Overview
Multi-Dimensional Homomorphisms (MDH) is an algebraic formalism, implemented as a DSL compiler, for AI and data-parallel computing in general. It expresses systematic de-composition and re-composition of computations across the memory and core hierarchies of modern parallel architectures, including GPUs and CPUs.
Ultimate MDH Goals
- Performance: achieve performance competitive to hand-optimized solutions
- Portability: target arbitrary parallel architecture
- Productivity: free user from hardware and optimization details
MDH Compiler Structure
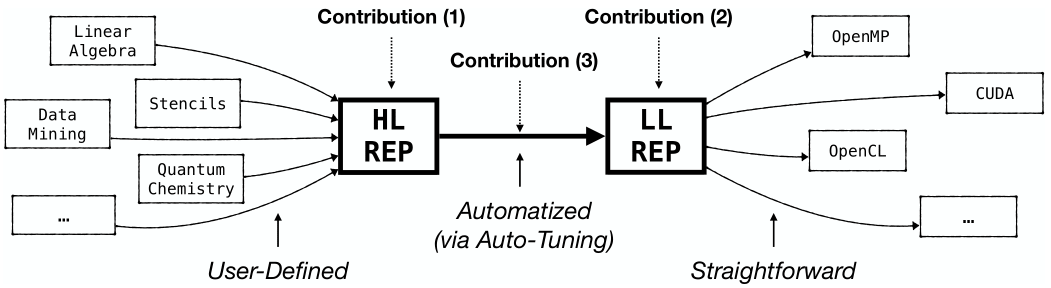
The MDH approach formally introduces and implements program representations on different abstraction levels and automatic transformations between them.
MDH Program Representations
- High-Level Program Representation (
HL-IR) expresses data-parallel computations agnostic of hardware and optimization details - Low-Level Program Representation (
LL-IR) expresses device- and data-optimized data movement and parallelization optimizations - Code-Level Program Representation (
CL-IR) expresses data-parallel computations in an imperative style
MDH Program Transformations
- High-Level → Low-Level (
HL➜LL): based on auto-tuning, using the Auto-Tuning Framework (ATF) - Low-Level → Code-Level (
LL➜CL): shifts paradigm from functional to imperative - Code-Level → Code-Level (
CL➜CL): applies standard code-level optimizations (e.g., loop unrolling) - Code-Level → Backend (
CL➜{…}): lowers to executable target code (such as CUDA, OpenMP, and OpenCL) - Backend → Backend (
{…}➜{…}): target-specific optimizations (e.g., exploiting warp-level operations on NVIDIA GPUs)
Experiments
Experiments show results on GPUs and CPUs that are competitive with, and sometimes better than, state-of-practice approaches, including NVIDIA cuBLAS/cuDNN and Intel oneMKL/oneDNN which are hand-optimized libraries provided by vendors.
Getting Started
(Our MDH implementation will be open-sourced on GitHub.)
Code Examples
From the following code examples, the MDH compiler fully automatically generates device- and data-optimized, executable program code, e.g., in CUDA for NVIDIA GPUs, OpenMP for CPUs, or OpenCL for multiple kinds of architectures.
MDH’s Python-Based User Interface
-
Matrix-Vector Multiplication (MatVec) expressed in MDH’s high-level program representation:
def matvec( T:BasicType, I:int,K:int ):
    @mdh()
    def mdh_matvec():

        @scalar_function()
        def mul( out:Scalar[T], inp:Scalar[T,T] ):
            out['w'] = inp['M'] * inp['v']

        @pw_custom_func()
        def add( res, lhs,rhs ):
            res['w'] = lhs['w'] + rhs['w']

        return (
            out_view[T]( w = [lambda i,k: (i)] ),
              md_hom[I,K]( mul, (cc,pw(add)) ),
                inp_view[T,T]( M = [lambda i,k: (i,k)] ,
                               v = [lambda i,k: (k)  ] )
        )
The above defined
matvecfunction is used as follows:# MatVec on 1024x1024-sized input matrix and 1024-sized vector (both containing fp32 values) matvec__fp32__1024_1024 = matvec( fp32, 1024,1024 ) # CUDA host code ASSERT_DRV(cuda.cuInit(0)) device = ASSERT_DRV(cuda.cuDeviceGet(device_id)) # Get MDH "CUDA Module" for MatVec (using ATF-tuned optimizations) cuda__matvec__fp32__1024_1024 = mdhc.compile( computation=matvec__fp32__1024_1024, backend=CUDA( device ), tuner=pyATF( CUDARuntimeProfiler(), evaluations(1000) ) ) # MDH CUDA Module: compile CUDA code a100_cuda__matvec__fp32__1024_1024 = cuda__matvec__fp32__1024_1024.nvcc_compile( arch='compute_80' ) # MDH CUDA Module: run MatVec on M,v to obtain w w = np.random.rand(1024).astype(np.float32) M = np.random.rand(1024, 1024).astype(np.float32) v = np.random.rand(1024).astype(np.float32) a100_cuda__matvec__fp32__1024_1024.run( w,M,v ) # MDH CUDA Module: destroy module a100_cuda__matvec__fp32__1024_1024.destroy() -
Jacobi-1D (Jacobi1D) expressed in MDH’s high-level program representation:
def jacobi1d( T:BasicType, I:int ): @mdh() def mdh_jacobi1d(): @scalar_function() def f_j1d( out:Scalar[T], inp:Scalar[T,T,T] ): out['y'] = (inp['x', 1] + inp['x', 2] + inp['x', 3]) / 3.0 return ( out_view[T]( y = [lambda i: (i)] ), md_hom[I]( f_j1d, (cc) ), inp_view[T]( x = [lambda i: (i + 0), lambda i: (i + 1), lambda i: (i + 2)] ) )The above defined
jacobi1dfunction is used as follows:# Jacobi1D on a 1024-sized input vector (containing fp32 values) jacobi1d__fp32_1024 = jacobi1d( fp32, 1024 ) # CUDA host code ASSERT_DRV(cuda.cuInit(0)) device = ASSERT_DRV(cuda.cuDeviceGet(device_id)) # Get MDH "CUDA Module" for Jacobi1D (using ATF-tuned optimizations) cuda__jacobi1d__fp32_1024 = mdhc.compile( computation=jacobi1d__fp32_1024, backend=CUDA( device ), tuner=pyATF( CUDARuntimeProfiler(), evaluations(1000) ) ) # MDH CUDA Module: compile CUDA code a100_cuda__jacobi1d__fp32_1024 = cuda__jacobi1d__fp32_1024.nvcc_compile( arch='compute_80' ) # MDH CUDA Module: run Jacobi1D on x to obtain y y = np.random.rand(1024).astype(np.float32) x = np.random.rand(1026).astype(np.float32) a100_cuda__jacobi1d__fp32_1024.run( y,x ) # MDH CUDA Module: destroy module a100_cuda__jacobi1d__fp32_1024.destroy()
MDH’s MLIR-Based User Interface
-
func.func @main() { %M = memref.alloc() : memref<128x64xf32> %v = memref.alloc() : memref<64xf32> %w = mdh.compute "mdh_matvec" { inp_view = [ [ affine_map<( i,k ) -> ( i,k )> ], [ affine_map<( i,k ) -> ( k ) > ] ], md_hom = { scalar_func = @mul, combine_ops = [ "cc", ["pw",@add] ] }, out_view = [ [ affine_map<( i,k ) -> ( i )> ] ] } { inp_types = [ f32, f32 ], mda_size = [ 128,64 ], out_types = [ f32 ] }( %M,%v ) : ( memref<128x64xf32> , memref<64xf32> ) -> memref<128xf32> return }Functions
@muland@addare straightforward, user-defined functions for computing scalar multiplication or scalar addition, respectively (both not shown for brevity). Functionsccandpware pre-implemented combine operators for computing concatenation (cc) or point-wise operations (pw), respectively. -
func.func @main() { %x = memref.alloc() : memref<64xf32> %y = mdh.compute "mdh_jacobi1d" { inp_view = [ [ affine_map<( i ) -> ( i+0 )> , affine_map<( i ) -> ( i+1 )> , affine_map<( i ) -> ( i+2 )> ] ], md_hom = { scalar_func = @jacobi, combine_ops = [ "cc" ] }, out_view = [ [ affine_map<( i ) -> ( i )> ] ] } { inp_types = [ f32 ], mda_size = [ 62 ], out_types = [ f32 ] }( %x ) : (memref<64xf32>) -> (memref<62xf32>) return }Function
@jacobiis the Jacobi-specific computation (not shown for brevity), andccis a pre-implemented combine operator for computing concatenation.
Automatic Parallelization & Optimization
As an alternative to DSL programs in MDH’s high-level programming representation, MDH supports as input additionally straightforward (annotated) sequential program code:
def matvec( T:BasicType, I:int,K:int ):
@mdh( out( w = Buffer[T] ) ,
inp( M = Buffer[T], v = Buffer[T] ) ,
combine_ops( cc, pw(add) ) )
def mdh_matvec( w, M,v ):
for i in range(I):
for k in range(K):
w[i] = M[i,k] * v[k]
This program is equivalent to the DSL-based MDH program for MatVec above and is used the same way:
# MatVec on 1024x1024-sized input matrix and 1024-sized vector (both containing fp32 values)
matvec__fp32__1024_1024 = matvec( fp32, 1024,1024 )

# CUDA host code
ASSERT_DRV(cuda.cuInit(0))
device = ASSERT_DRV(cuda.cuDeviceGet(device_id))

# Get MDH "CUDA Module" for MatVec (using ATF-tuned optimizations)
cuda__matvec__fp32__1024_1024 = mdhc.compile(
    computation=matvec__fp32__1024_1024,
    backend=CUDA( device ),
    tuner=pyATF( CUDARuntimeProfiler(), evaluations(1000) )
)

# MDH CUDA Module: compile CUDA code
a100_cuda__matvec__fp32__1024_1024 = cuda__matvec__fp32__1024_1024.nvcc_compile( arch='compute_80' )

# MDH CUDA Module: run MatVec on M,v to obtain w
w = np.random.rand(1024).astype(np.float32)
M = np.random.rand(1024, 1024).astype(np.float32)
v = np.random.rand(1024).astype(np.float32)
a100_cuda__matvec__fp32__1024_1024.run( w,M,v )

# MDH CUDA Module: destroy module
a100_cuda__matvec__fp32__1024_1024.destroy()
Schedule-Based Optimization Process
MDH optionally allows expert users to incorporate knowledge into the optimization process using its scheduling language. By incorporating the user into the optimization process, we enable two major advantages over the standard MDH workflow:
- better optimization, as an auto-tuning system might not always make the same high-quality optimization decisions as a human expert
- faster auto-tuning, as some (or even all) optimization decisions might be made by the expert user and thus are not left to the costly auto-tuner
(An example scheduling program follows soon)
Selected Publications
-
R. Schulze, A. Rasch
From Algebraic Data-Parallel Expressions to Imperative Parallel Code via Multi-Dimensional Homomorphisms
IEEE/ACM International Symposium on Code Generation and Optimization (CGO 2027), (to appear)
Paper -
A. Rasch
(De/Re)-Composition of Data-Parallel Computations via Multi-Dimensional Homomorphisms
ACM Transactions on Programming Languages and Systems (TOPLAS 2024) – Presented at PLDI’24 conference
Paper Slides -
A. Rasch
Full Version: (De/Re)-Composition of Data-Parallel Computations via Multi-Dimensional Homomorphisms
arXiv 2024
Paper Slides -
A. Rasch, R. Schulze, D. Shabalin, A. Elster, S. Gorlatch, M. Hall
(De/Re)-Compositions Expressed Systematically via MDH-Based Schedules
ACM SIGPLAN International Conference on Compiler Construction (CC 2023)
Paper Slides
Selected Talks
-
Systematic Code Generation for ML Computations based on Multi-Dimensional Homomorphisms
Compilers for Machine Learning (C4ML 2026); Sydney, Australia
Slides -
Reduction-Aware Directive-Based Programming via Multi-Dimensional Homomorphisms
The International Conference for High Performance Computing, Networking, Storage, and Analysis (SC 2025); St. Louis MO, USA
Slides
- A. Rasch, R. Schulze
MDH+ATF: Code Generation & Optimization for Deep-Learning Computations
Compilers for Machine Learning (C4ML 2025); Las Vegas NV, USA
Slides
- A. Rasch, R. Schulze, S. Gorlatch
Using MLIR for Multi-Dimensional Homomorphisms
Google SIG MLIR Open Design Meeting 2020, (invited talk)
Slides Talk
Citations
Please use the following citations when referring to MDH:
- Formalism & Design
@article{10.1145/3665643, author = {Rasch, Ari}, title = {(De/Re)-Composition of Data-Parallel Computations via Multi-Dimensional Homomorphisms}, year = {2024}, publisher = {Association for Computing Machinery}, address = {New York, NY, USA}, issn = {0164-0925}, url = {https://doi.org/10.1145/3665643}, doi = {10.1145/3665643}, journal = {ACM Trans. Program. Lang. Syst.}, month = {may}} - Scheduling Language
@inproceedings{10.1145/3578360.3580269, author = {Rasch, Ari and Schulze, Richard and Shabalin, Denys and Elster, Anne and Gorlatch, Sergei and Hall, Mary}, title = {(De/Re)-Compositions Expressed Systematically via MDH-Based Schedules}, year = {2023}, isbn = {9798400700880}, publisher = {Association for Computing Machinery}, address = {New York, NY, USA}, url = {https://doi.org/10.1145/3578360.3580269}, doi = {10.1145/3578360.3580269}, booktitle = {Proceedings of the 32nd ACM SIGPLAN International Conference on Compiler Construction}, pages = {61-72}, numpages = {12}, keywords = {GPU, scheduling languages, deep learning, CPU}, location = {Montr\'{e}al, QC, Canada}, series = {CC 2023} } - Automatic Parallelization and Optimization
@INPROCEEDINGS{mdpoly,
  author={Rasch, Ari and Schulze, Richard and Gorlatch, Sergei},
  booktitle={Proceedings of the International Workshop on Polyhedral Compilation Techniques (IMPACT 2020)},
  title={\texttt{md\_poly}: A Performance-Portable Polyhedral Compiler based on Multi-Dimensional Homomorphisms},
  year={2020},
  volume={},
  number={},
  pages={1-4}}
Contact
Ari Rasch
| Focus: | Project Lead |
| Affiliation: | University of Münster |
| Email: | a.rasch@uni-muenster.de |
| Website: | arirasch.net |
Richard Schulze
| Focus: | Technical Lead |
| Affiliation: | University of Münster |
| Email: | r.schulze@uni-muenster.de |
| Website: | richardschulze.net |
You can also find us on  Discord.